Agent memory · Note 01
From retrieval to state: rethinking long-term memory for AI agents
Abstract
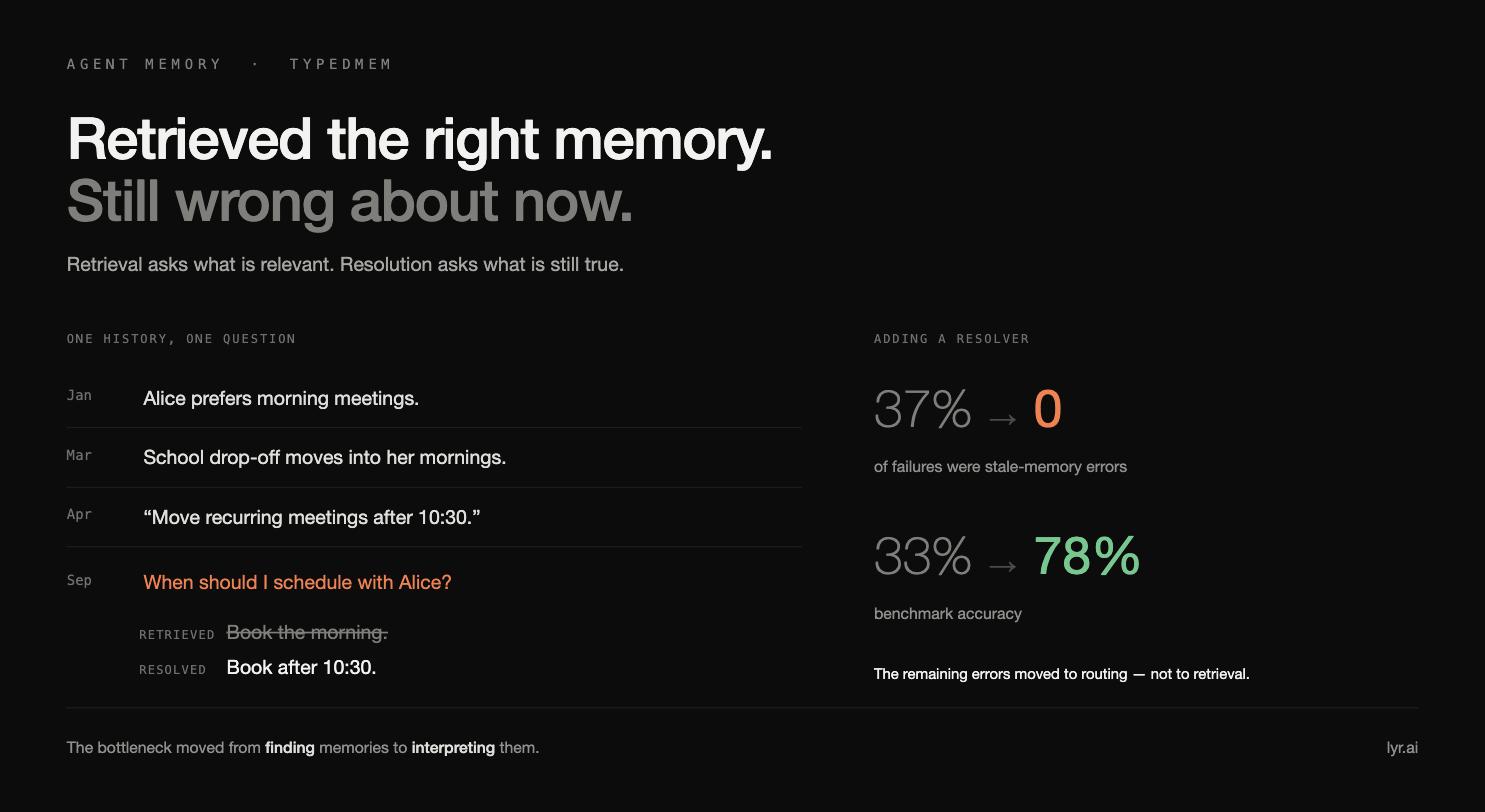
Most agent-memory systems start with a familiar pipeline: store past observations, embed them, retrieve semantically relevant memories, and place them back into context. This works well when the problem is remembering a fact that appeared earlier. It becomes less reliable when the past contains multiple versions of the same fact, contradictory statements, decisions that supersede earlier preferences, or goals that evolve across sessions.
I encountered this while building TypedMem and ReliAgent Bench. In the benchmark, adding more retrieval was not enough. A memory system also needed to distinguish different kinds of remembered information, reason about temporal validity, and resolve which retrieved evidence should govern the current answer. In one iteration, adding a resolver reduced stale-memory errors from 37% to zero and overall benchmark accuracy improved from 33% to 78%; after that, the dominant errors shifted toward routing rather than retrieval itself.
This changed how I think about long-term agent memory. The central problem is not simply “Which past text is relevant?” It is “Given everything that has happened, what should the agent believe now?”
1. Retrieval is necessary, but it is not memory
Consider a simple history:
January     Alice prefers morning meetings.
March       Alice starts taking her daughter to school in the morning.
April       Alice asks to move recurring meetings after 10:30.

September   When should I schedule a meeting with Alice?
A vector search may correctly retrieve:
Alice prefers morning meetings.
That memory is semantically relevant. It is also no longer sufficient to answer the question.
The system needs to understand that later events changed the operational meaning of the earlier preference. More retrieval does not necessarily fix this, because the retrieval system may simply return both statements. The difficulty lies downstream:
- Which statement is current?
- Did the later statement replace the earlier one, or merely qualify it?
- Was it a temporary exception?
- Does an implicit decision override an explicit older preference?
This distinction becomes more important as memory accumulates over weeks or months.
2. Memory has different semantics
Another problem appears when every memory is represented as interchangeable text. These statements are not the same kind of information:
“I like window seats.”
“I booked seat 14A for tomorrow.”
“My flight was cancelled.”
“Next time, avoid the 6 a.m. flight.”
“I usually travel with my daughter.”
One describes a preference, another an event, another a state transition, another a decision, and another potentially persistent personal context. Treating all five as embeddings in one undifferentiated pool discards information that becomes useful later.
EVENT        Flight cancelled ──────────── historical fact
                                           remains true about the past

STATE        Lives in San Jose ──────→ Lives in Seattle
                                           ↑ newer state wins

PREFERENCE   Likes mornings ────────→ prefers after 10:30
                                           ↑ may supersede or qualify

DECISION     Use provider A ────────→ switch to provider B
                                           ↑ explicit replacement
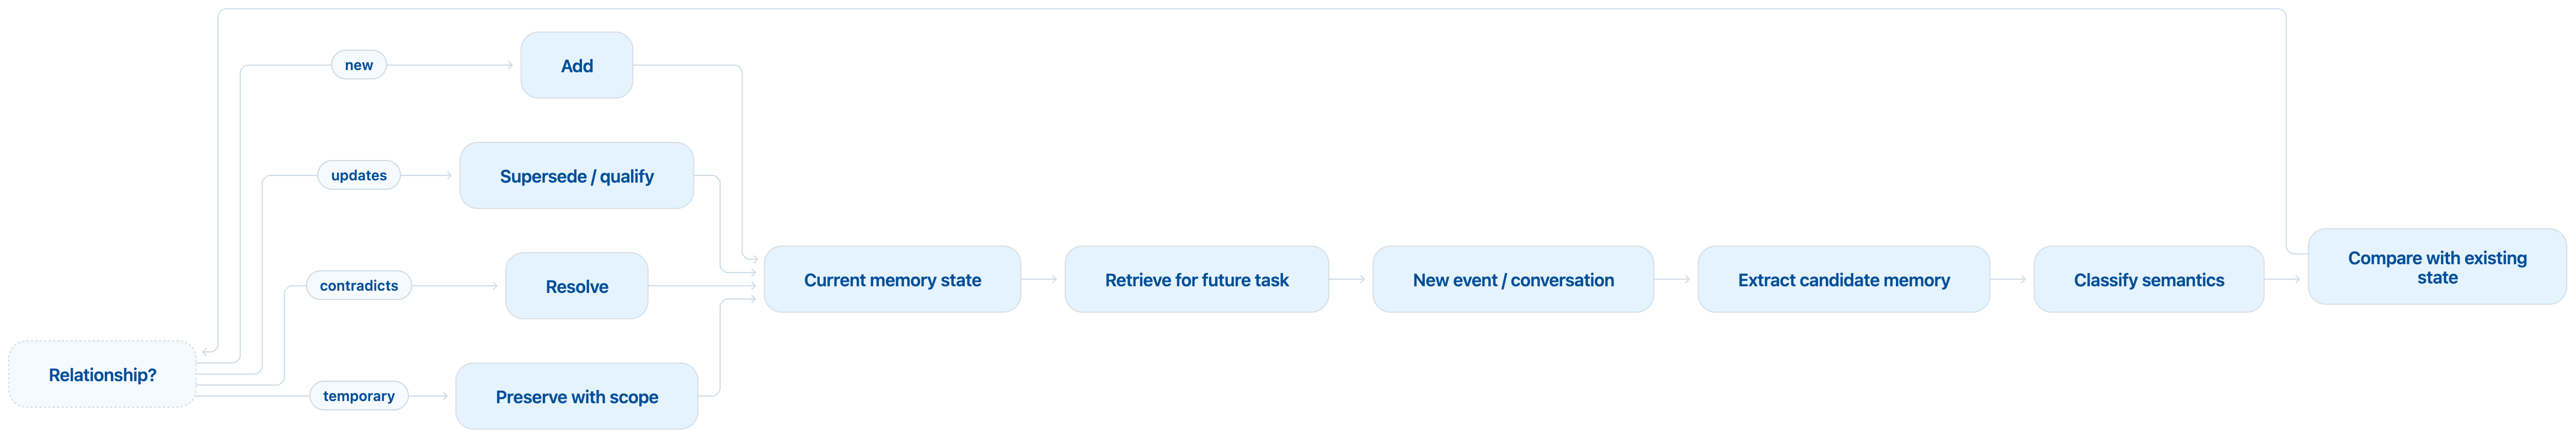
Different memory types have different persistence and supersession semantics. TypedMem therefore began from a different representation: memory items carry semantics that help determine how they should be retrieved and resolved. The exact schema matters less than the principle that an event, a preference, a decision, and a changing state should not necessarily obey the same update rules.
3. The hard case is history, not storage
The benchmark work made this clearer. ReliAgent Bench grew from relatively simple retrieval cases into cases involving long histories, contradictions, cross-session information, implicit goals, mixed memory types, and implicit decisions.
A representative failure is not “the system couldn’t find the relevant memory.” It is closer to:
Retrieved:
  ✓ relevant old preference
  ✓ relevant new decision
  ✓ relevant intervening event

Answer:
  ✗ uses the wrong one
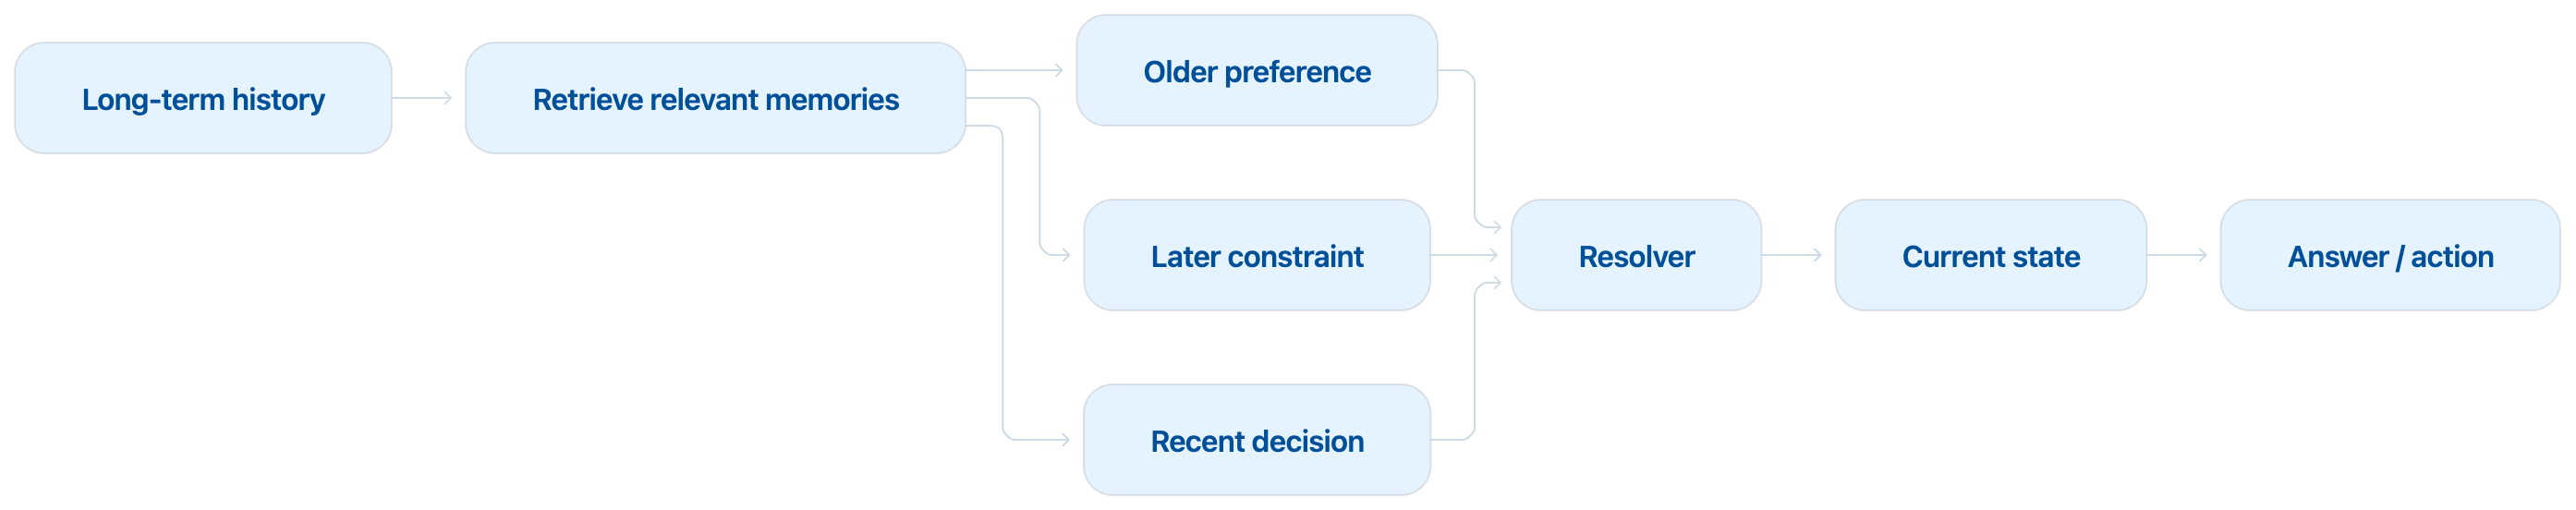
The information was available. The memory system failed to construct the correct current interpretation from it. This led to a pipeline that separates several responsibilities:
query → router → filters → vector search → ranking → resolver → current answer
The resolver was particularly revealing. In one benchmark iteration, stale-memory errors accounted for 37% of failures. After adding explicit resolution logic, that category fell to zero. Overall accuracy moved from 33% to 78%, while the dominant remaining errors shifted toward routing.
I don’t read those numbers as evidence that this particular architecture is the final answer. They illustrate something more useful: once retrieval becomes reasonably good, the bottleneck can move from finding memories to interpreting them correctly.
4. Memory should represent change
This leads to a different mental model. Instead of
past text → vector database → similar text
I increasingly think about long-term memory as a sequence of states and the transitions between them: an event moves the state, a decision replaces part of it, new evidence corrects it, a preference update qualifies it.

The contrast is worth stating plainly:
Traditional memory     [chunk] [chunk] [chunk] [chunk]
                           \      |      /       /
                              similarity search

State-oriented memory  S₁ ──event──→ S₂ ──decision──→ S₃ ──update──→ NOW
5. A useful memory system should be able to explain itself
If the system answers “schedule the meeting after 10:30,” it should ideally be possible to reconstruct why:
Older memory        "prefers morning meetings"
        ↓
Later constraint    "school drop-off in mornings"
        ↓
Explicit decision   "move recurring meetings after 10:30"
        ↓
Current answer      "schedule after 10:30"
This is useful for more than explainability. It lets us distinguish failures that a single retrieval score collapses into one number:
- retrieval failure — relevant evidence was never found;
- routing failure — the query searched the wrong kind of memory;
- ranking failure — the right evidence was retrieved but buried;
- resolution failure — conflicting evidence was found but interpreted incorrectly;
- representation failure — the memory system did not encode the distinction needed to resolve the case.
That decomposition made debugging TypedMem substantially more useful than treating memory quality as a single retrieval score.
6. What should an agent actually remember?
This is the question I think TypedMem should ultimately answer.
Storing everything is attractive because it avoids making an irreversible decision at write time. But unlimited storage does not solve memory. It moves the difficulty to retrieval and resolution, while increasing irrelevant context and contradiction. Aggressive summarization has the opposite problem: it can compress history efficiently while silently removing exactly the detail needed to reinterpret a later event.
The design I am exploring sits between these extremes. Raw history can remain available as evidence, while a smaller structured memory layer maintains the information expected to remain useful across sessions: persistent facts, changing states, preferences, decisions, goals, and the relationships between their updates. The resulting architecture looks less like a notebook and more like a continuously updated model of the user or environment.
7. What I want to measure next
The next stage should move beyond aggregate benchmark accuracy. A useful long-term memory system should answer at least four measurable questions.
First, temporal correctness asks whether the system answers using the information that is valid at the requested time rather than merely retrieving a semantically similar statement.
Second, contradiction resolution asks whether later evidence, explicit corrections, and superseding decisions are handled consistently.
Third, causal traceability asks whether an answer can be traced to the sequence of memories and updates that produced the current state.
Finally, long-horizon stability asks whether these properties continue to hold as histories grow across many sessions rather than only in short synthetic examples.
This is also why I do not want TypedMem to become a collection of domain-specific schemas. A useful abstraction should work across personal memory, parenting histories, pet histories, reading notes, and agent execution logs without requiring a bespoke ontology for every application. The goal is not to know in advance every category of fact a user might care about. It is to represent enough structure about time, type, change, and evidence that the system can reason about what remains true.
Conclusion
I started TypedMem thinking primarily about retrieval: how to find the right piece of a long history when an agent needs it.
The benchmark failures pushed me toward a different view. Retrieval is only one stage of memory. Long-term memory also requires deciding how new information changes old information, which statements remain valid, which decisions supersede earlier preferences, and how the current state can be reconstructed from its history.
The question I now care about is therefore not “can the agent remember what I said?” It is “can the agent maintain a coherent understanding of what is true now — and explain how it got there?”
That is the direction TypedMem is moving. It is also the same question as Experiment 01, asked from the other end: that post asks which part of a trajectory determines the future, this one asks which part of a history determines the present.
Written while building AgentSeism. New posts by RSS.